treatment record
glitch-06
The whole published pass so far - 6,251 frames, 4.3 minutes - with BOTH readings in one overlay: all-COCO segmentation contours and id boxes, plus pose skeletons and face mesh on the figures the prompts say should not be there. Composited 'under', so the HUD is drawn onto the plate before displacement and the blockouts cut and carry it.
- status
- preferred
- upstream
- pass-02 frames 1–6,251
- evidence
- Video only. No frame sequence was written, so the encode is the record.
Its window on pass 2's full 43,200-frame axis.
what it looks like · 12 frames
 f0000010:00
 f0005530:23
 f0011290:47
 f0016811:10
 f0022571:34
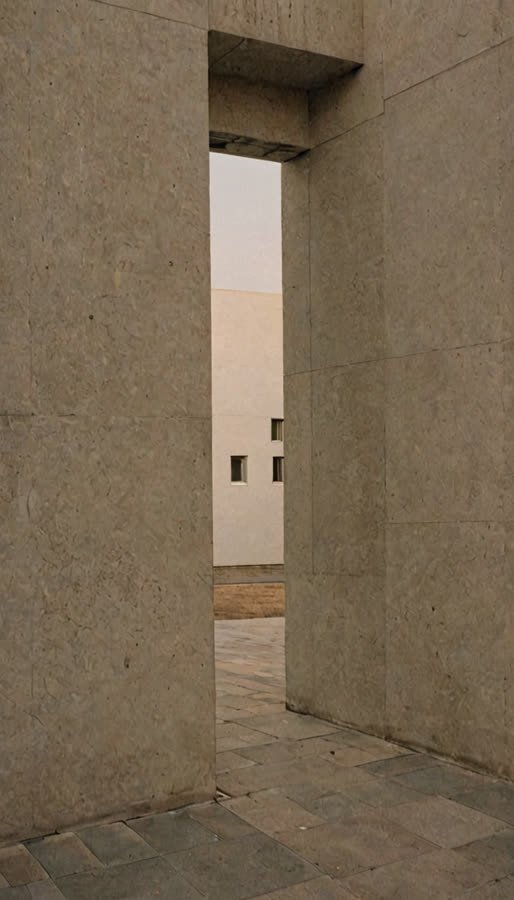 f0028331:58
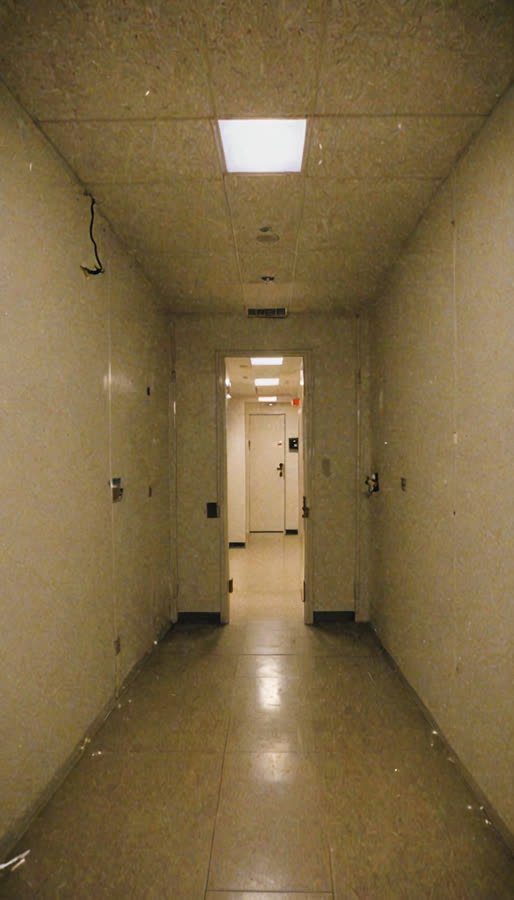 f0033852:21
 f0039612:45
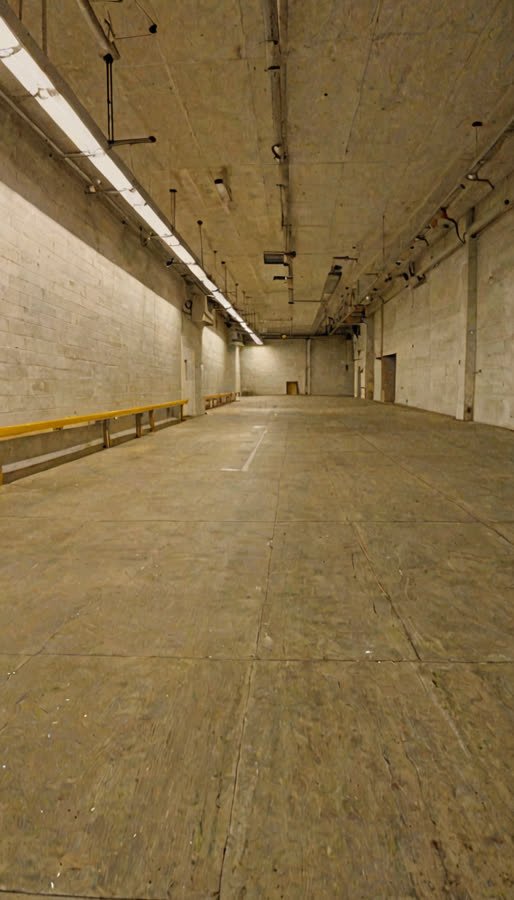 f0045373:09
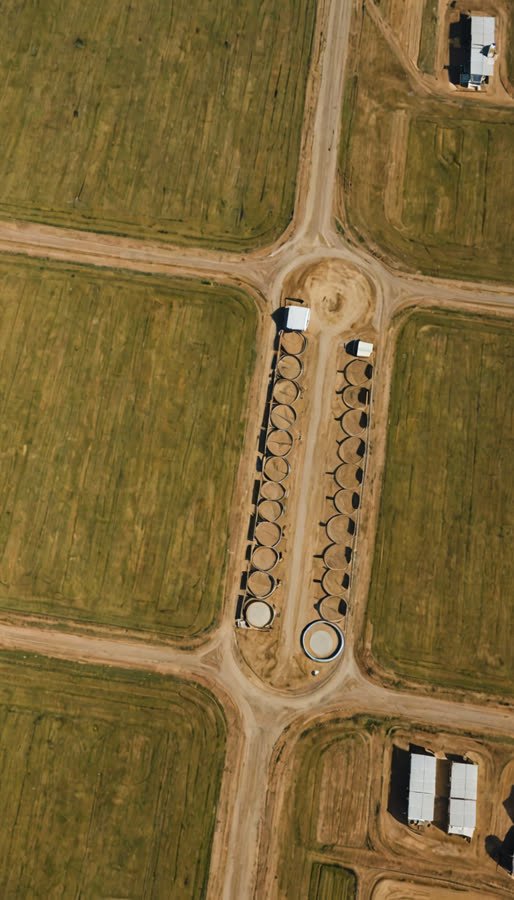 f0050893:32
 f0056653:56
 f0062414:20
This treatment kept no sampled frames of its own, so these are the source frames it consumed — pass-02 1–6,251, before the treatment was applied.
Two detections files merged into one overlay, which no single detect.py run produces: --draw-mask needs masks and --draw-skeleton needs keypoints, and one model gives one or the other. The merge is a union with pose ids namespaced 'p<id>' because the two runs use independent trackers - see cv.merged_from.
Upstream
- pass
- pass-02
- frames
- 1–6,251
- source
regenerable: hstack of passes/pass-02/{frames,text} 1-6251 (image left, text right)- source sha256
41d8807682ce
Regenerating the source
ffmpeg -framerate 24 -start_number 1 -i frames/frame_%06d.png -framerate 24 -start_number 1 -i text/frame_%06d.png -frames:v 6251 -filter_complex '[0:v][1:v]hstack=inputs=2' -c:v prores_ks -profile:v 4 -pix_fmt yuv444p10le source.mov |
Render
- composite
- under
- device
- cpu
- frames
- 6,251
- clip length
- 4 m 20 s
- time to render it
- 42 m 21 s
- chunking
- 160-frame windows, 40 of them, 124-frame lead-in discarded
- overlay draws
- box, mask, skeleton, face_mesh
- overlay hold
- 1 frame
- stroke / bracket / label floor
- 5 / 56 / 4,800 px²
Displacement layers
| grid | max offset | angle | sparsity | jitter | hold | stagger | seed | envelope |
|---|---|---|---|---|---|---|---|---|
| 4×3 | 32 | 90° | 0.5 | 0.8 | 8 | 0.6 | 5 | none |
| 8×7 | 22 | 0° | 0.8 | 0.8 | 6 | 0.5 | 9 | none |
| 20×18 | 14 | 0° | 0.93 | 0.8 | 4 | 0.8 | 13 | none |
What the detector found
- model
yolo11n-seg.pt + yolo11n-pose.pt- confidence floor
- 0.15
- detections
- 2,738
- per frame
- 0.438
| label | detections | |
|---|---|---|
| person | 748 | |
| train | 321 | |
| bench | 288 | |
| clock | 171 | |
| refrigerator | 137 | |
| suitcase | 102 | |
| truck | 102 | |
| car | 96 | |
| airplane | 60 | |
| kite | 49 |
Outputs
| file | frames | geometry | runtime | bytes | sha256 |
|---|---|---|---|---|---|
previews/glitch-06.under-contours-skeletons.f000001-006251.mp4 | 1–6,251 | 1536x1344 | 4 m 20 s | 1.3 GB | 8060d8ab14d5 |
Named and hashed, not hosted. Nothing in this repository is a master.
Provenance
This treatment was run as a local process rather than dispatched through the mesh, so it has no task id, no lease and no event trail. That is a gap in the record, and it is recorded as one.
Note
No frame sequence on this run, deliberately: writing 6,251 full-resolution PNGs measured 2.3 frames/s, ~45 minutes on top of a ~42 minute gather, for an output a look is not judged on. This is look development and the video is the deliverable. Re-render with --frames-dir once the look is locked; the source and detections are recorded, so it reproduces exactly.